
- TOC {:toc}
This report investigates the performance of different aggregation methods for forecasting competition assessment, using the RCT-A dataset from the HFC competition. I evaluated the five aggregation methods and proposed an improvement based on the best-performing method.
The dataset was analysed using the data.table R package, which allows fast and memory efficient handling of data.
Skills: R data.tables, RMarkdown
Project 2: Web Scraping Tabular Data with Python
In this project, I performed web scraping on the Wikipedia page for “List of Old-Growth Forests” to collect, clean, and analyze forest data from various regions worldwide. Using Python’s BeautifulSoup library, I extracted data from multiple tables with inconsistent formatting and missing information, employing custom functions to standardize the dataset for analysis. I used techniques for handling data inconsistencies, structuring a custom scraping pipeline, and conducting exploratory data analysis to answer questions about forest distribution by country and region.
Skills: Python, BeautifulSoup, web scraping, data cleaning, regex, exploratory data analysis
Project 1: qPCR Analysis Pipeline
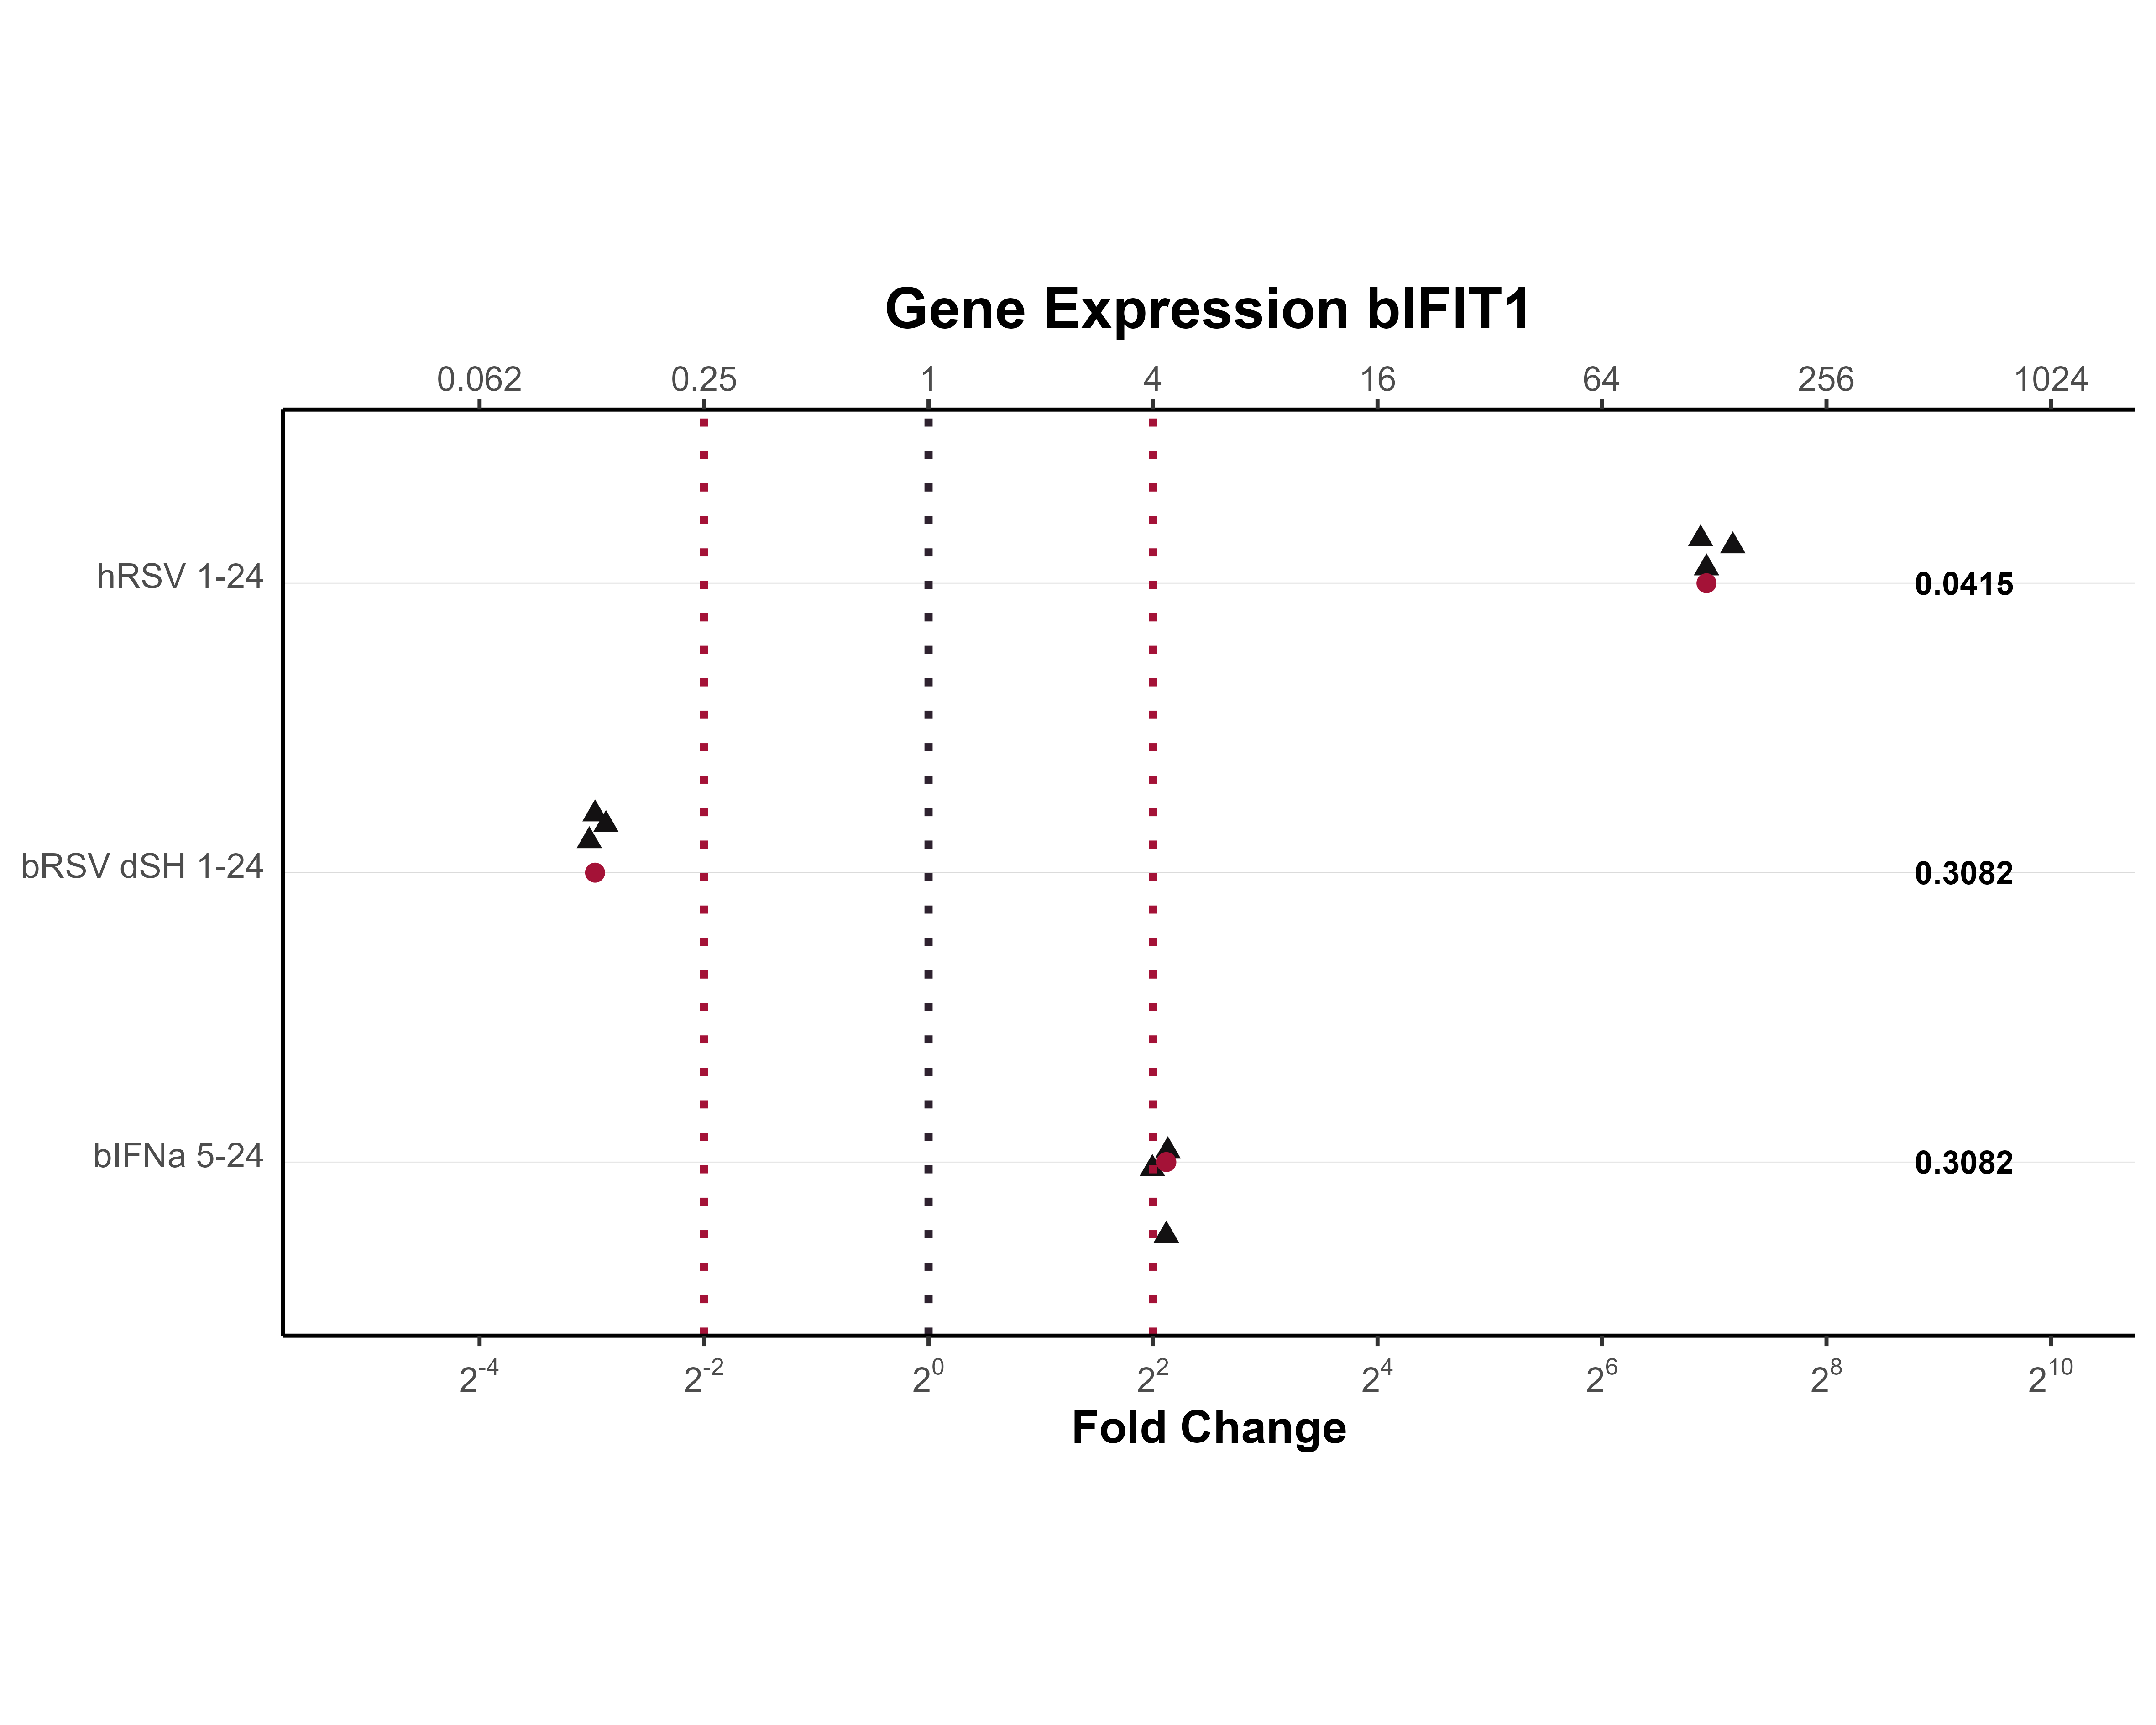
I developed a robust qPCR analysis pipeline in R to address the challenges of varying amplification efficiencies across different primers. The pipeline constructs a standard curve for accurate copy number extrapolation, normalizes target gene data using log2 deltaCt values of a housekeeping gene, and outputs adjusted copy numbers for reliable comparison across experimental conditions. Using R and the tidyverse, I automated data manipulation, statistical analysis, and visualization within an RMarkdown document, producing a reproducible and transparent workflow for quantitative gene expression analysis in life sciences.
Skills: R (tidyverse), Data Wrangling and Transformation, Statistical Analysis, Data Visualization (ggplot2), Scientific Data Interpretation, RMarkdown Automation and Reproducibility
Project 2: RNAseq Pipeline
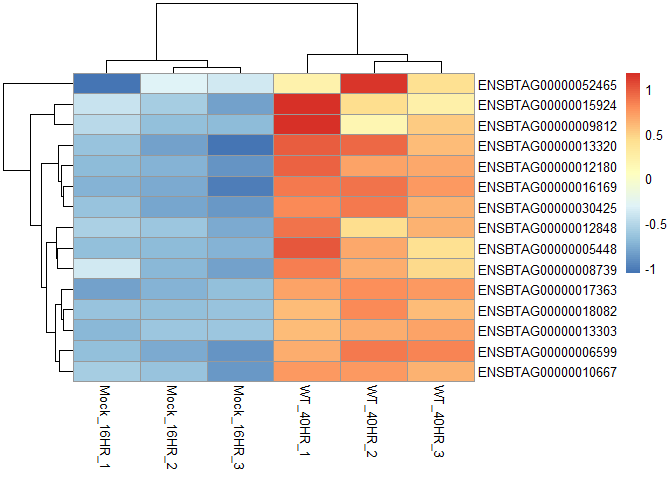
I conducted a differential expression analysis on RNA-seq data to identify genes with significant expression changes between treatment conditions. Using the DESeq2 package, I applied techniques such as normalization, dispersion estimation, and variance stabilization to process the raw counts, ensuring robust statistical testing. Exploratory analyses included principal component analysis (PCA) and sample distance clustering, which validated sample groupings and data quality. I further enhanced the results by adding gene annotations, preparing the data for downstream gene ontology (GO) enrichment analyses.
Project 3: PhD Thesis
This repository contains the LaTeX source files and supporting materials for my PhD thesis, which was successfully defended at the University of Cambridge. The project demonstrates my ability to:
- Write in LaTeX: I used LaTeX for the entire document creation process, showcasing my proficiency with the platform, particularly for managing complex academic documents.
- Work with Large Documents: The thesis, comprising multiple chapters, appendices, figures, tables, and references, highlights my ability to structure and organize extensive documents efficiently.
- Academic/Medical Writing: The content focuses on advanced topics in molecular pathology, pharmacology, and virology, evidencing my ability to communicate complex scientific research clearly and effectively.
- File and Project Management: This repository illustrates my ability to manage a large-scale writing project, including version control, organizing LaTeX files, and handling the compilation of a document with multiple components.
Skills: LaTex, Git, GitHub, academic writing, file management